11 Concept Testing Tools: Software and AI Platforms
Compare 11 concept testing tools by how they run studies, find audiences and charge. Includes published price examples, a sample budget and a supplier brief.
Concept testing tools help research and product teams compare proposed offers, investigate buyer reactions and choose what to develop next. Compare the exposure design, audience, diagnostic questions and research responsibilities before choosing a platform or a partner.
Choose the decision and what each buyer will see before choosing a concept-testing tool. LaunchPad offers a guided one-concept-per-person test; Qualtrics organizes recurring internal programs; Pollfish supports flexible consumer designs and targeting; Zappi provides innovation diagnostics and relevant norms; PickFu supports a focused relative choice with written reasons. Ask each shortlisted provider to demonstrate your complete card, eligible audience and required output under the plan you would buy.
Removing a function changes the complete offer. Our feature-removal research guide compares what customers give up with the replacement offer before a team ships the change.
Published by Sapien. We include our own platform and compare providers by research job, evidence source and deliverables.
Eleven concept testing tools: the purchase comparison
This unranked shortlist combines the five workflows explored below with six additional routes. Match the audience source and study design before comparing a licence, sample charge or managed-project quote. The guide is based on documented offerings, not a head-to-head product test.
Tool | Method, source and cost model |
|---|---|
Qualtrics | Recurring concept programs and flexible human survey studies; Edge Audiences is a separately scoped modeled route. Platform subscription, sample and study support need separate confirmation. |
SurveyMonkey LaunchPad | Guided one-concept-per-person product tests with human responses. Price the selected solution and purchased targeting; its project overview supplies the estimated results date. |
Pollfish | Flexible human consumer surveys and monadic or comparative designs. Confirm the eligible audience, per-study sample price and managed-service requirements before launch. |
Zappi | Repeatable innovation tests and relevant norms. Subscription plus research credits and separately scoped services; confirm whether the selected test collects human answers or uses a modeled route. |
PickFu | Human votes and written reasons for a focused relative choice. Surveys start at $1 per response; final price depends on targeting, complexity and sample. Pay-as-you-go and subscriptions are available. |
Conjointly | Human surveys with product-concept, monadic and advanced methods. Annual software licence plus separately scoped sample and services. |
Kantar Marketplace | Standardized concept testing and a separately scoped ConceptEvaluate AI route. The method and response source depend on the product selected; confirm the complete per-study quote. |
Attest | Consumer concept studies using human survey responses. A separate audience per concept supports independent exposure; confirm targeting, credits and support. |
quantilope | Automated concept studies with A/B monadic, conjoint and MaxDiff workflows. Scope human-panel work separately from the Category Twins modeled route. |
Suzy | Concept exploration and evaluation within a consumer research platform. Confirm design, eligible audience access and subscription scope. |
Sapien | Managed research using a data-grounded synthetic population. Agree complete concepts, audience grounding, study outputs, validation and the next human or transaction check in the project scope. |
For turnaround, compare the complete schedule: stimulus preparation, eligibility or grounding, fieldwork, analysis and the revision you need. A fast platform response is different from a finished research recommendation. Our concept testing guide covers the study decisions behind this shortlist.
Consumer panels and automated concept testing
Which concept testing tool includes consumer panels and reporting?
SurveyMonkey LaunchPad Product Concept Testing offers purchased responses from its panel alongside automated scorecards and exportable reports. You can also use your own contacts. Audience access and study access are separate cost items, so confirm the eligible buyers, completed responses per concept and required report in the actual quote.
Ask to see results by concept and relevant buyer group, with question wording, full rating distributions, valid bases and open-answer reasons. A panel's overall size doesn't show whether it can reach your category buyers. For an independent two-concept comparison, confirm that different buyers evaluate each offer before relying on a combined dashboard score.
Are automated concept testing tools the same as synthetic research?
No. Automation can organize a study, score responses and produce a report while people still answer the questions. A modeled route produces estimates without collecting a new human response for that concept. Ask which source supplies each result and whether AI assists the analysis or replaces respondents for the quoted task.
LaunchPad's automated scorecards accompany feedback from real people. Kantar describes ConceptEvaluate AI as a model trained on consumer concept-test surveys that screens ideas without showing them to consumers. Compare those offers by the evidence your development decision needs, keeping human and modeled response bases separate.
What concept testing tools cost
A concept-testing tool's price can cover software access, recruited responses or a managed study. The useful comparison is the total cost of answering your question with the required buyers. A low price per response won't help if the quoted study exposes everyone to both offers when you need an independent first reaction to each.
These public price examples were checked on October 25, 2026. Dollar amounts below are US dollars. They show different charging models, so the rows aren't a price ranking.
Tool | Published price and what still needs pricing |
|---|---|
PickFu | Surveys start at $1 per response. The final charge depends on the question type, complexity, targeting and sample. Price your actual questionnaire and audience before treating that starting rate as a budget. |
Conjointly | Professional costs $2,895 per team per year, with panel responses charged separately. Its page reports a $1.55 average self-serve bid per completed response from recent orders. That average isn't a quote for your category or eligibility criteria. |
LaunchPad | SurveyMonkey Product Concept Testing is sold per study without a subscription. Targeted responses cost extra; you can also use your own contacts. Get the study charge and audience estimate together for your configured test. |
For the other shortlisted tools and a managed Sapien study, ask which work each would cover for the same decision. Keep a recruited-human study and a modeled screen on separate lines: the evidence and remaining validation work differ. Our market research pricing guide explains the broader cost components when you also need research design and interpretation.
Independent appeal or a relative choice?
Imagine you are choosing between two finished household starter-kit offers. You need to know whether each is understandable and worth developing at its proposed price. The brief below is a proposed study, with audience numbers and progression cutoffs to set from your actual decision. Assigning one complete offer per buyer supports independent appeal. Showing both offers and asking for a preference answers a different question: which is favored within that comparison set.
A finished brief makes concept tools comparable
Commission field | Filled two-concept brief |
|---|---|
Decision | Which household starter-kit offer is understandable and worth taking to development at its stated price? |
Stimuli | Two finished cards with matched detail: contents, use occasion, price, preparation and image treatment. Save both versions. |
Audience | Eligible category buyers in the intended market; confirm qualifying criteria and feasible recruitment before buying. |
Exposure | Randomly assign one complete offer per buyer for independent appeal. No prior exposure to the other card. |
Question order | Unaided understanding first; then price-specific intent, reasons and the agreed diagnostics. |
Primary output | Each offer’s response distribution and valid base, plus the prespecified between-offer comparison. |
Development gate | An understood, feasible offer with adequate appeal under the team’s commercial criteria. A misunderstanding triggers revision. |
Working record | Exact cards, assignment rule, question wording, eligible bases, exclusions, reasons and included iteration. |
Each field names a requirement you can demonstrate before committing to the study.
If neither offer is attractive, a forced choice still produces a winner. If one buyer sees both, the first card can shape expectations for the second. Those designs can be useful, but a tool label such as “concept testing” does not settle the interpretation. Write the exposure rule and primary outcome into the procurement brief.
For the finished-offer case, assess a compatible monadic workflow. If the immediate task changes to choosing between two pack treatments to refine, a focused choice test may be enough. Preserve price, contents and competing context when they are part of the decision; a packaging preference collected without them should retain that narrower meaning.
How many people are in a two-concept quote?
Return to the two household starter kits. Suppose the team sets aside a planning allowance of 200 eligible completed responses per concept. This is an illustrative budget assumption, not a sample-size recommendation. Size the real study for the difference you need to detect and the audience comparisons you plan to use.
Our concept-test sample-size guide works through the difference worth detecting, the valid base per offer and the buyer group that can set the study budget.
For this illustration, both kits are one-time $29 online purchases with shipping included. A contains a 500 mL all-purpose cleaner, a 500 mL dish soap and two cleaning cloths. B contains an empty 500 mL spray bottle, four all-purpose-cleaner refills that each make 500 mL when mixed with water, and two cleaning cloths. Neither is a subscription. The study compares the complete offers, including the ready-to-use contents versus refills; it won't isolate a separate effect of the bottle or wording.
Quoted design | What the count actually contains |
|---|---|
Independent exposure | 200 people see A and a different 200 see B: 400 people, one concept each, 200 evaluations per concept. |
Sequential exposure | The same 200 people evaluate A and B in balanced order: 200 people and 400 evaluations. A person's second evaluation follows exposure to another offer. |
Direct preference | 200 people see A and B and choose between them: 200 people and 200 choices within the displayed pair. This doesn't give either offer an independent first-reaction score. |
“400 concept evaluations” could describe either of the first two rows. It doesn't tell you whether 400 different people participated. Confirm the unique participant count, completed responses per concept and exposure order before comparing totals. Our monadic testing guide explains when separate groups or repeated exposure fit the decision.
The same issue appears inside segments. If 400 people complete the independent study and 100 currently buy your brand, the current-customer result has 100 people in total, split across concepts. It doesn't have 400 responses per concept or per segment. Specify the required completed base for each comparison instead of assuming an overall quota supplies it.
Concept testing tools and companies compared
Use the comparison to choose the workflow you want demonstrated, then inspect the documented scope below.
Tool | The decision and workflow to assess |
|---|---|
Qualtrics | Recurring concept work with a saved concept database and program dashboards. Confirm exposure and consistent measures across waves. |
LaunchPad | Independent appeal through Product Concept Testing's one-concept-per-person design. Check the eligible audience and benchmark fit. |
Pollfish | A consumer study needing flexible design or category targeting. Check the purchase criteria and whether required diagnostics need managed services. |
Zappi | Innovation work where relevant norms and diagnostics inform the next development step. Keep the specific solution and response source explicit. |
PickFu | A focused relative choice, such as packaging, with human votes and written reasons. Preserve the alternatives and audience behind the preference. |
The shortest useful shortlist contains the routes that can finish your decision. More features do not compensate for the wrong exposure rule or an audience that does not qualify.
Qualtrics: build a recurring internal program
Qualtrics Concept Testing Program organizes tests in a concept database and compares program scores in dashboards, with single or sequential exposure. Confirm recruitment, account access and comparable measures. Your database begins with your own tests; it is not automatically an external category benchmark.
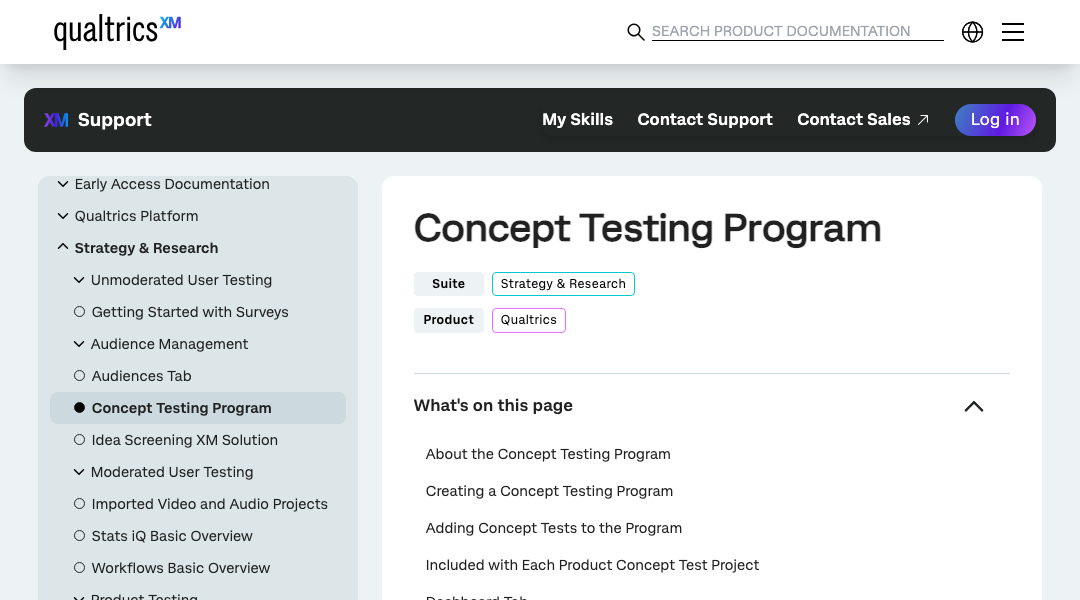
Open the full-size Qualtrics screenshot
LaunchPad: run a guided monadic product study
SurveyMonkey LaunchPad offers industry benchmarks, significance scorecards and reusable exports. Product Concept Testing shows one concept per person, using your contacts or purchased human responses. Check benchmark fit and targeting; targeted responses cost extra. Idea Screening instead uses sequential exposure.
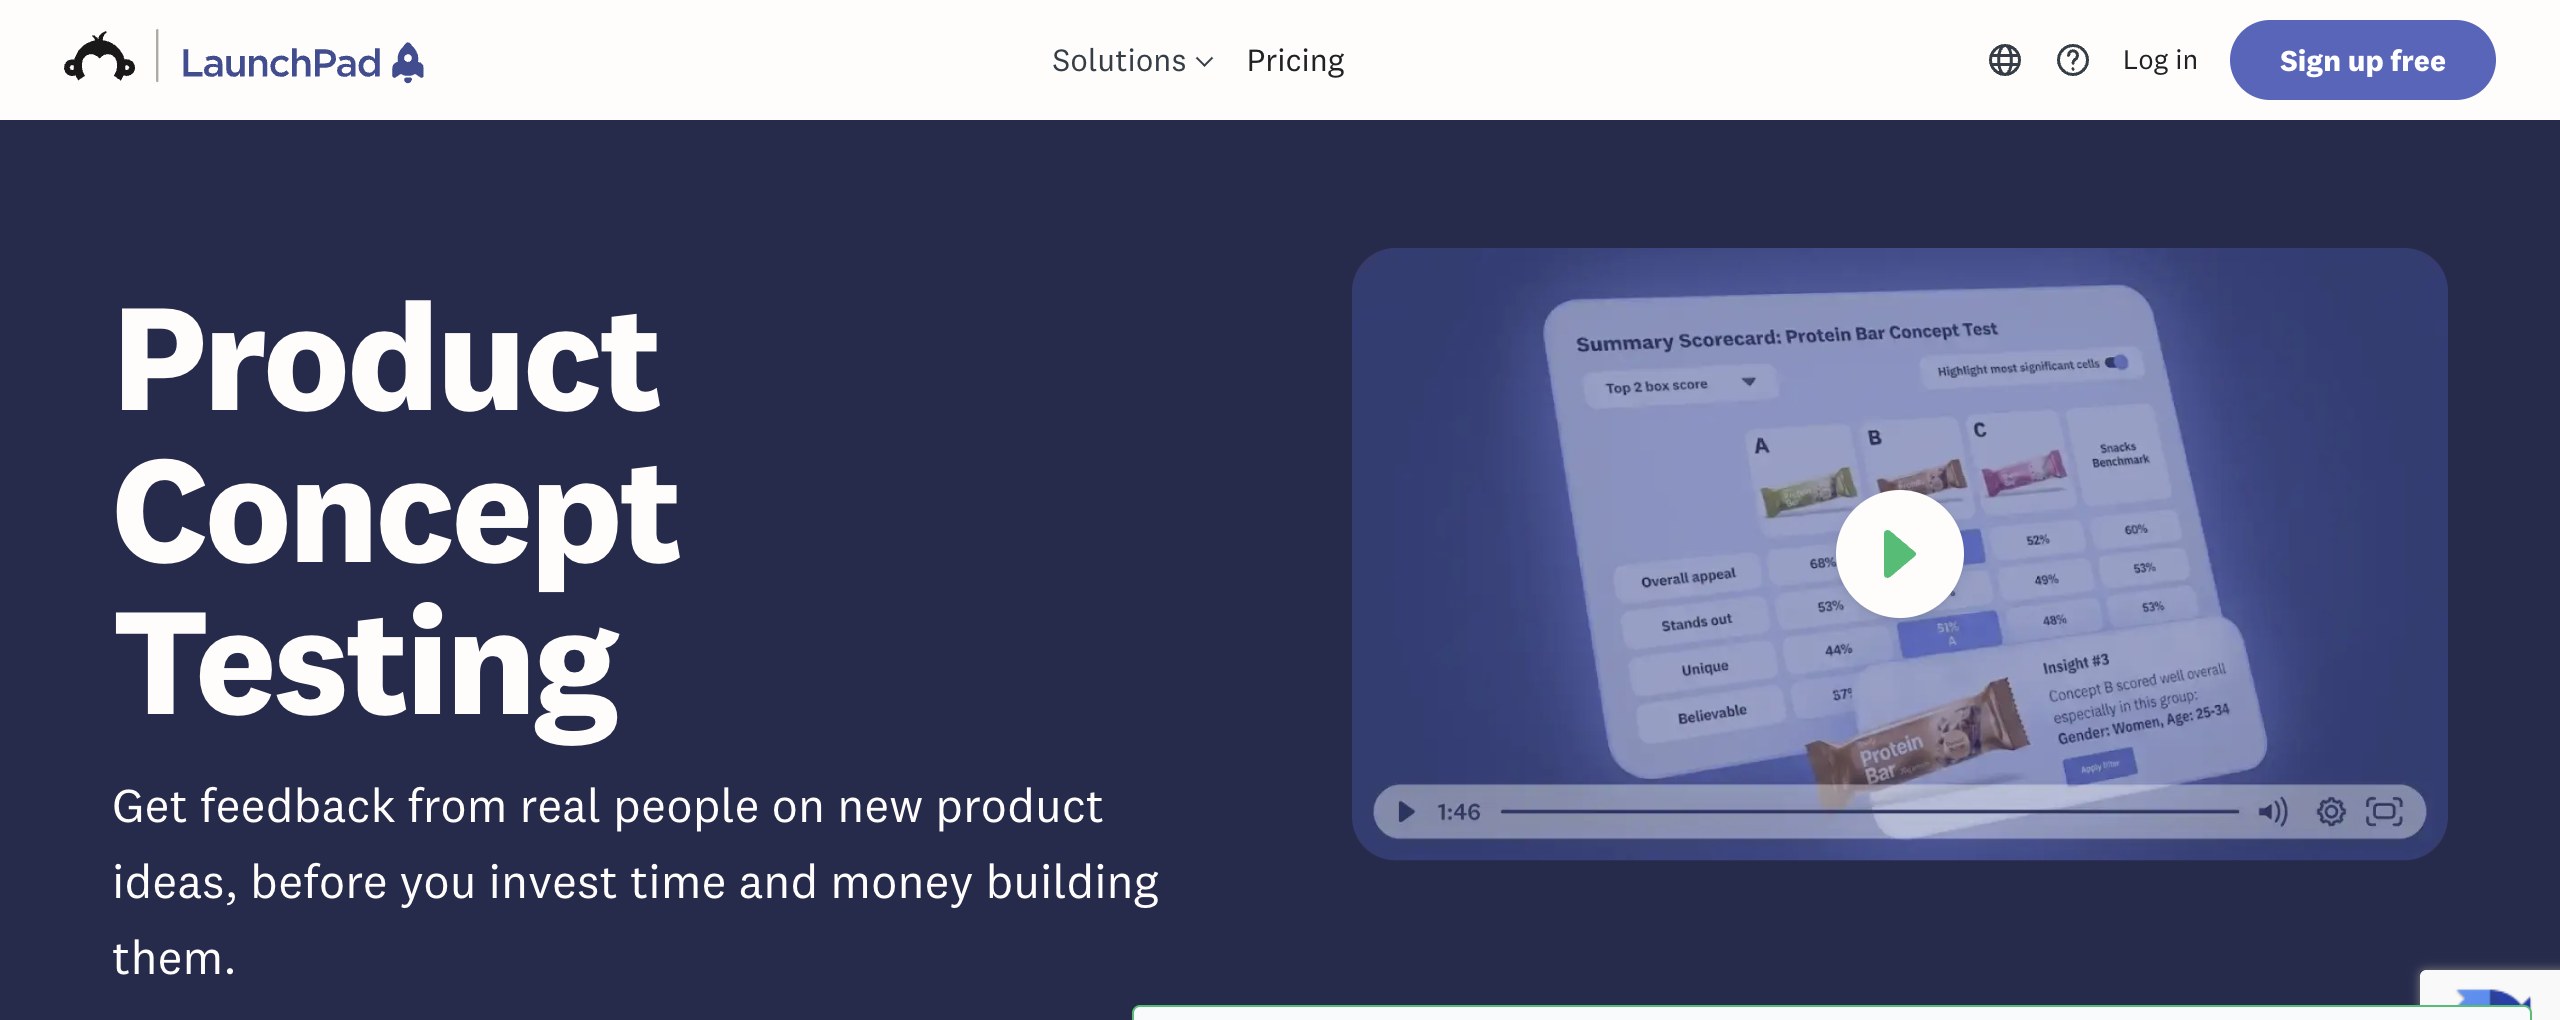
Open the full-size LaunchPad screenshot
Pollfish: tailor a consumer design and audience
Pollfish supports monadic or comparison designs with human consumer responses and targeting, including purchase-history criteria. Confirm which verified purchase criteria cover your category. Image heatmaps require managed services; overall panel scale does not establish your eligible base.
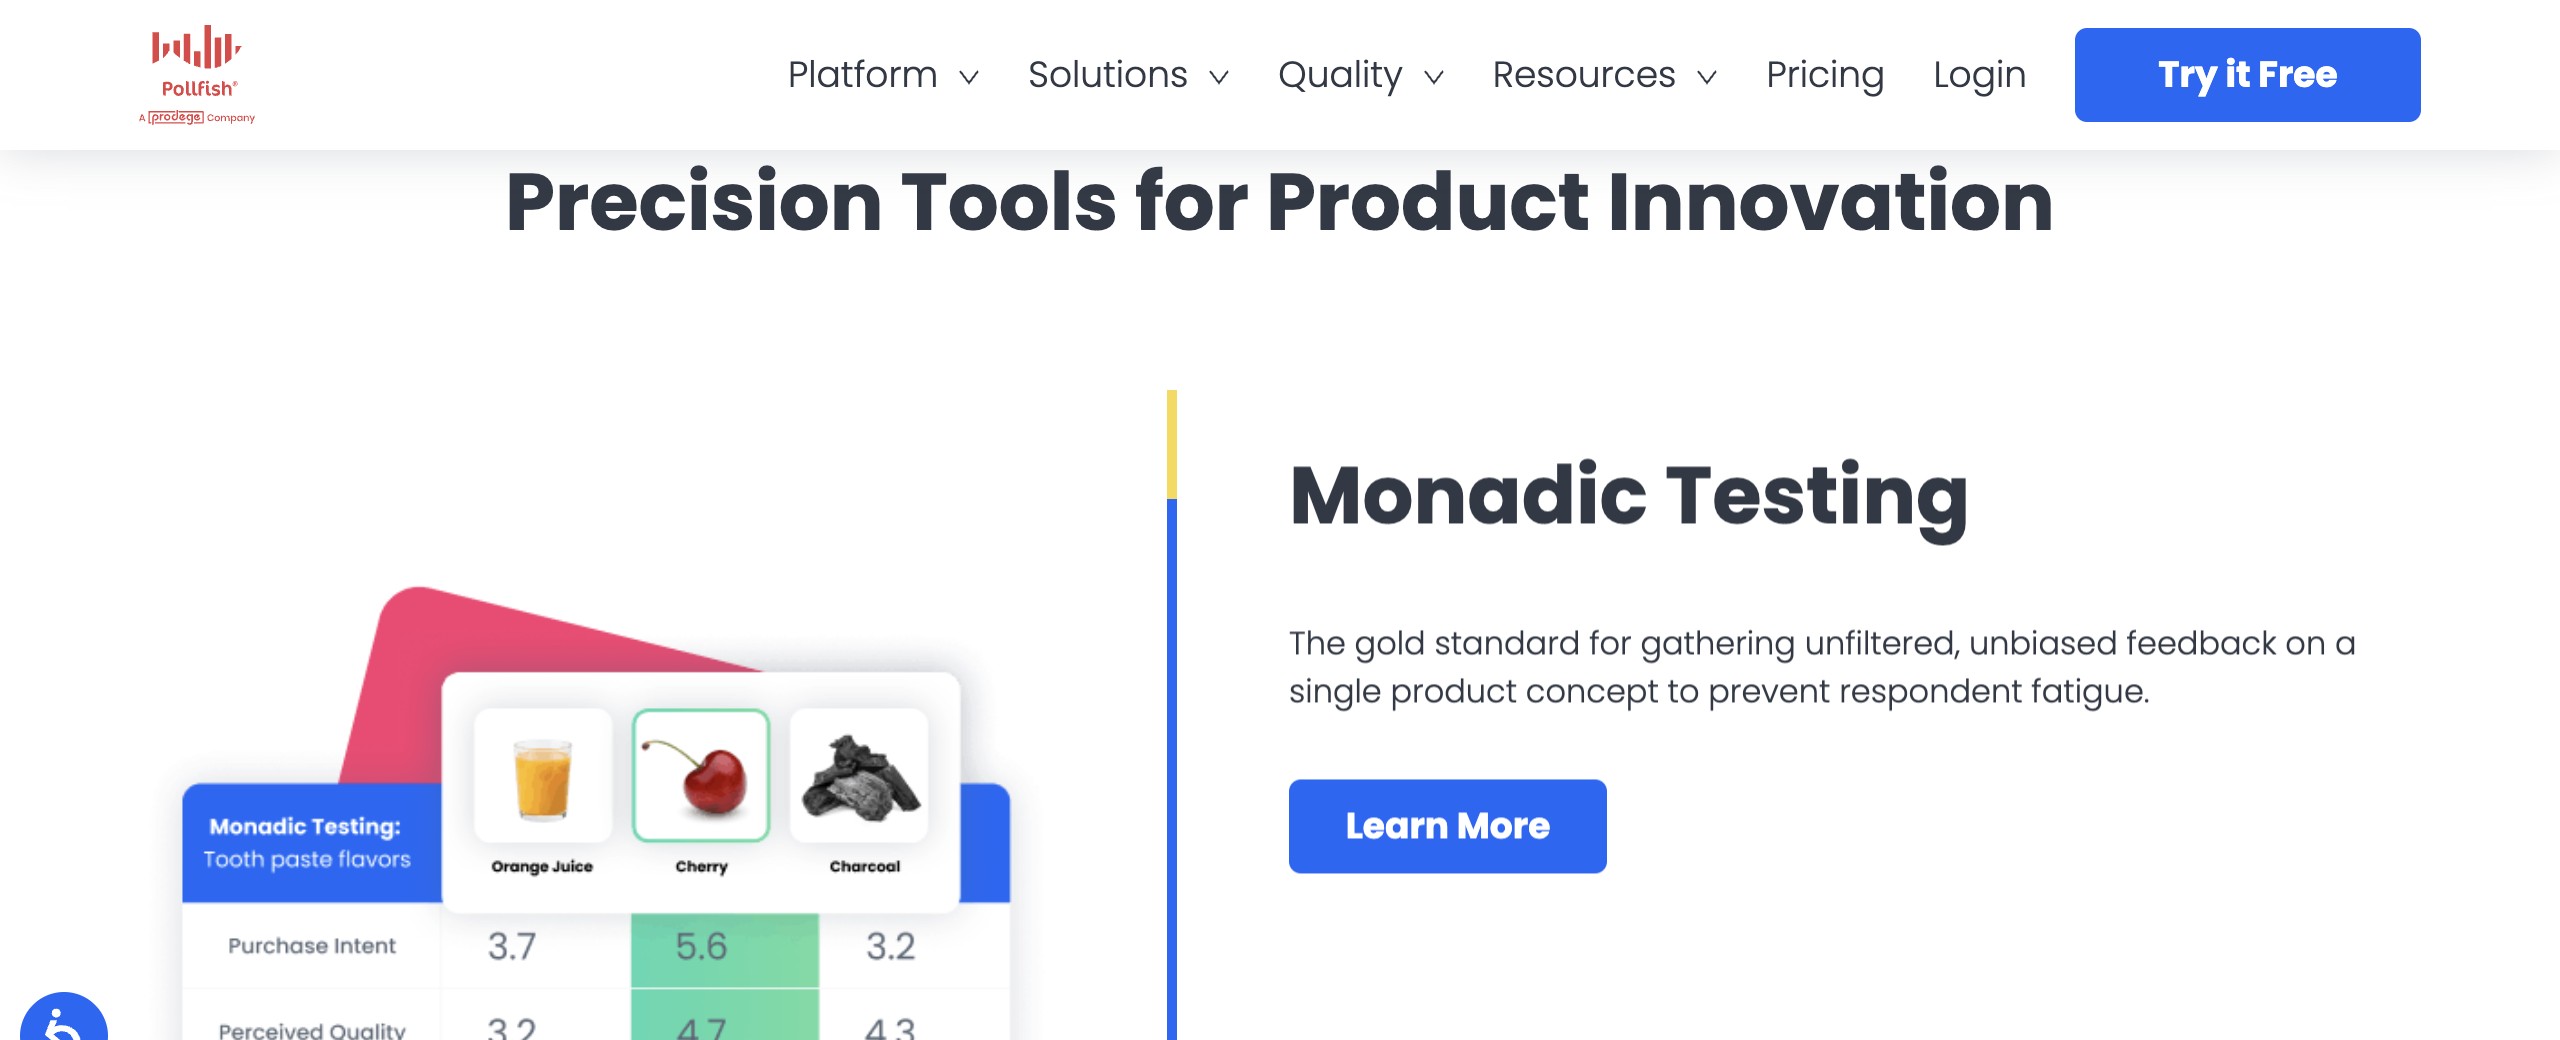
Open the full-size Pollfish screenshot
Zappi: add innovation diagnostics and relevant norms
Zappi provides norms, open-response diagnostics and visual heatmaps for recurring innovation work. Confirm the specific concept solution and response source. Norm relevance depends on category and audience, and separately advertised synthetic idea screening uses a different evidence route.
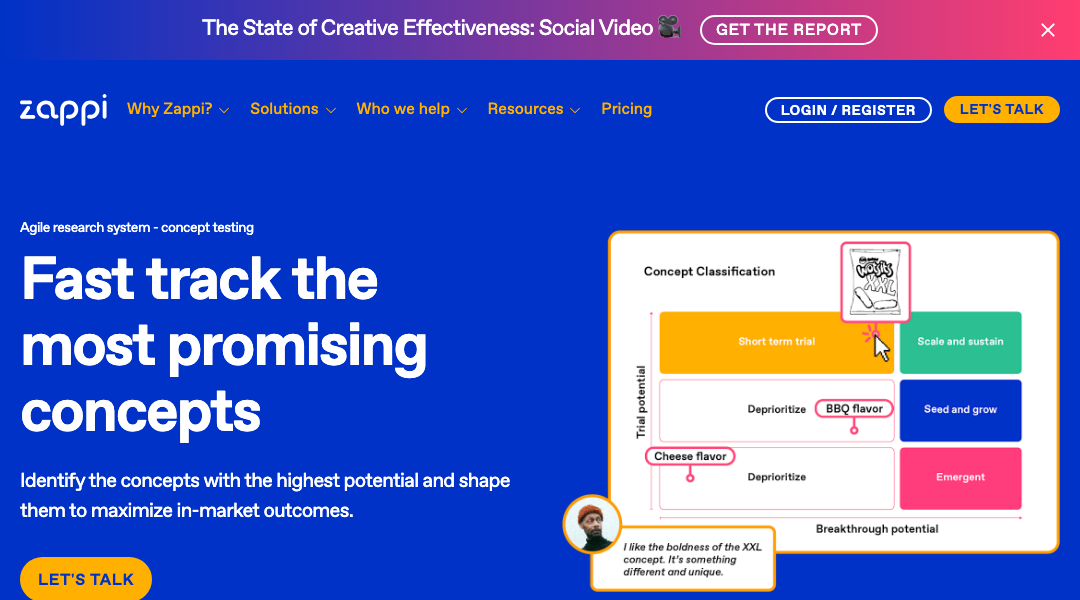
Open the full-size Zappi screenshot
PickFu: investigate a focused relative choice
PickFu supplies human consumer votes with written reasons; select targeting traits and study type at setup. Confirm niche-audience eligibility. A vote is relative to the options shown, so it does not replace a full monadic program or establish sales.
Official pages were checked on October 10, 2026. This is a documented-scope comparison, with no account trial or independent quality ranking. Demonstrate the actual requirement under the plan you would purchase. A product page can describe a capability without establishing that every account, audience or study includes it.
LaunchPad’s Product Concept Testing shows one concept per person; its Idea Screening uses sequential exposure. The solution help covers setup. Selecting between those workflows is part of study design. Qualtrics’ concept program organizes your own tests; an initially empty program database should not be sold internally as an external category norm.
Zappi’s Concept Test method documentation describes a monadic workflow with a Key Takeout open response before core metrics. The documented flow places heatmap interaction before Key Takeout; it does not automatically provide an unaided first response. Its Behavior Change output is an 11-point likelihood rating for a specified action. Inspect that question and its position when piloting the finished offers: the label describes stated intention, rather than an observed purchase. Confirm that the quoted configuration preserves the required stimulus and question order.
Related guides: market research companies.
Planning a study? Copy our free market research brief template and send the same decision, audience and output requirements to every provider.
Six further workflows for the shortlist
Conjointly
Human surveys with product-concept, monadic and advanced methods. Annual software licence plus separately scoped sample and services.
Open the full-size Conjointly screenshot
Kantar Marketplace
Standardized concept testing and a separately scoped ConceptEvaluate AI route. The method and response source depend on the product selected; confirm the complete per-study quote.
Attest
Consumer concept studies using human survey responses. A separate audience per concept supports independent exposure; confirm targeting, credits and support.
quantilope
Automated concept studies with A/B monadic, conjoint and MaxDiff workflows. Scope human-panel work separately from the Category Twins modeled route.
Suzy
Concept exploration and evaluation within a consumer research platform. Confirm design, eligible audience access and subscription scope.
Sapien
Managed research using a data-grounded synthetic population. Agree complete concepts, audience grounding, study outputs, validation and the next human or transaction check in the project scope.
For B2B concepts, demonstrate buying-role eligibility
For a professional concept, ask the provider to demonstrate the buying situation and audience eligibility rather than rely on a job-title filter. Identify who uses the offer, who sponsors it and who reviews the purchase, with the category experience each needs to evaluate it. Preserve role-level understanding and objections in the output; an overall appeal score can conceal a blocker for one decision-maker.
Our B2B market research guide covers buying-context evidence. Our B2B message testing guide follows a promise across roles. Carry those constraints into the complete concept and its development gate. For a modeled audience, agree how professional context is grounded and validated; generated specialist responses are not testimony from current buyers.
A packaging choice is a narrower tool job
In its provider-reported Angry Orange case, PickFu describes Thrasio using consumer panels and pet-owner feedback to test product images and packaging for an odor eliminator. For a relative creative comparison of that kind, use the actual alternatives and the intended audience's reasons to decide which treatment to develop.
For the household starter kits above, a packaging winner would still leave each priced offer's independent appeal unanswered. Use a focused comparison when the immediate decision is which image or pack treatment communicates the product better. Use the independent-exposure brief when deciding whether a complete offer deserves development. The case illustrates the first job; it does not establish the second or isolate a poll's contribution to sales.
For the narrower pack decision, our packaging design testing guide connects comprehension and preference findings to the artwork you should revise next.
Inspect one finding all the way back to the card
Use the filled brief above to request a demonstration or sample output. Start with the exact displayed card, then inspect the understanding answer, scoring rule and response base. Ask whether an eligible buyer saw only that concept and whether the measure followed the proposed order. The software should preserve the facts needed to reconstruct the conclusion.
Suppose intent is high but unaided answers describe a refill as an automatic subscription when the offer is one-off. Do not let an appealing aggregate erase that conflict. Inspect how often the interpretation occurs, under which stimulus and among which eligible buyers. A targeted wording repair followed by the same comprehension check is a more complete next step than progressing a misunderstood concept.
Ask for category distributions and reasons, rather than only an overall score. Retain the exact scale and base for any top-box or combined-category percentage. Confirm whether the export includes stimulus version, assignment, eligibility and special response states. These are proposed acceptance checks, not results of a product trial performed for this guide.
A norm adds context when the match is credible
LaunchPad and Zappi advertise benchmark or norm outputs. Their usefulness depends on category, audience, geography, concept stage, exposure and measure. Ask what is in the reference set and how it was collected. A finished priced offer compared with early unpriced ideas can produce a precise-looking percentile with limited decision value.
For a recurring internal program, comparability comes from consistent instruments and a saved change history. An unchanged score can conceal a shift in recruited buyers or stimulus detail. Build the internal reference deliberately and identify material breaks before comparing waves.
Even a well-matched norm does not settle feasibility or comprehension. A concept above the norm can still require a price explanation or preparation repair. Use the reference alongside the team’s commercial criteria and observed diagnostic evidence.
Before using a supplier percentile to advance an offer, use our concept testing benchmarks guide to check the reference population, question, response scale and comparison conditions.
Budget one complete study and one possible revision
LaunchPad describes pay-per-study access with targeted responses sold separately; the checked official page did not expose a reliable universal starting price. Get the required solution and eligible response quote together. A software headline without audience costs cannot price the finished comparison.
A $620 sample allowance isn't a $620 study
Using Conjointly's published $1.55 average bid only as an arithmetic illustration, 400 completed responses would mean a $620 sample allowance. If a new Professional license is required for the chosen workflow, the first-year license and that sample allowance add to $3,515. The table separates a first purchase from work inside a license term already paid for.
Budget case | License + sample allowance |
|---|---|
First study, new annual license | $2,895 + (400 × $1.55) = $3,515. |
Next study, active license | 400 × $1.55 = $620 additional sample allowance. |
Four studies, new annual license | $2,895 + (4 × 400 × $1.55) = $5,375 total; $1,343.75 allocated per study. |
The four-study average spreads one annual license across four studies within its term; the license remains a business cost when it's already paid. These are partial planning totals for one provider's charging model, not supplier quotes. They exclude your team's work, stimulus preparation, extra analysis or services, taxes and other applicable charges. Audience feasibility and the actual response bid still need checking. Treat four studies as four only if your team has four useful decisions to research; unused software capacity doesn't lower the cost of the one answer you need.
A follow-up also changes the budget. Repeating both concepts with 200 fresh people per concept adds another 400 completions, or $620 at the same illustrative bid, if it runs within the paid license term. A narrower retest may cost less, but ask what comparison it preserves. Recontacting the original people answers a different question from collecting an unexposed first reaction.
For any quote, write the total as required access + eligible sample + design and analysis + the agreed revision. Add the human or product validation you still need after a modeled screen. This makes the full research plan visible without pretending that every route produces the same evidence.
Cost component | Question to send |
|---|---|
Access | Which plan, solution or service is required? |
Audience | What does qualifying and collecting the required evidence cost? |
Design | Who prepares stimuli, instrument and assignment? |
Analysis | Which outputs and interpretation are included? |
Export/reuse | Can we inspect and retain stimuli, responses and calculations? |
Additional work | What does a revision, extra concept or follow-up cost? |
Specify valid answers per concept and any segment reads before asking for a quote. If a niche segment is a development gate, the overall sample cannot substitute for an adequate segment base. Include screeners, replacements, translation, card preparation, interpretation and the bounded follow-up you would run after a misunderstanding.
Pollfish’s advertised heatmaps require managed services. Zappi’s professional services and separately advertised synthetic screening also need explicit scope. PickFu’s human votes and written reasons fit a focused comparison; a demonstration simulation should not be treated as collected research. Clarify which evidence route the exact quote contains.
A quote brief you can send to the shortlist
For the starter-kit decision, adapt the following request to your actual audience and planned sample. Keep the two finished cards attached to the brief you send.
Decision and audience: We need to choose which of the two $29 household-cleaning starter kits deserves development. Quote an English-language study of U.S. adults who bought household-cleaning products in the past three months and share responsibility for choosing them. Confirm audience feasibility before fieldwork. For this planning quote, show 200 eligible completed responses per concept in separate groups; identify any additional base needed for the subgroup comparisons we request.
Study and delivery: Randomly assign each person to one card. Collect unaided understanding before intent ratings or explanatory prompts. Return the exact card version, question wording, scales, eligible and answering bases, exclusions, response distributions and coded reasons. Show how the findings change the development recommendation. Itemize access, recruitment, design, analysis, delivery date and a separately priced fresh-sample retest. Identify who owns each job and which work our team must supply.
If a supplier proposes a sequential comparison, a preference test or modeled respondents, ask for the revised design and price separately. A useful alternative can be worth buying; it should be evaluated on the question it answers. Accept the quote when the team can explain what decision the returned evidence will support, what the total includes and what still needs testing.
Concept testing companies: managed providers
A team can buy capable software and still lack someone to design the study or turn conflicting answers into a recommendation. When that responsibility is the missing purchase, compare the managed scope alongside the tools above. For a fuller comparison of managed responsibilities and researcher support, use our concept testing companies guide.
Company | Work to agree in the proposal |
|---|---|
Researcher-led custom design and analytical consulting. Confirm recruitment, fieldwork, interpretation and who resolves a misunderstood concept. | |
Standardized diagnostics with a serviced route covering setup, a dashboard, written evaluation and a researcher readout. Confirm the audience, modules and included iteration; self-serve and serviced scopes differ. | |
Concept optimization with portfolio, reference and consulting context. Inspect how the category and launch assumptions fit the reference evidence before using a forecast. | |
Choice-based diagnostics and acceptor profiles against current alternatives. Confirm the assisted or self-service arrangement and the evidence behind its indexes; assisted access alone does not establish full project ownership. |
Open the full-size Decision Analyst screenshot
Open the full-size NIQ BASES screenshot
Open the full-size Ipsos InnoTest screenshot
Zappi, covered above, also offers professional services for tailored solutions, audiences and program support. Keep the license, sample, custom work and interpretation distinct in the quote, and specify the response source.
Give each suitable provider the same complete cards, eligible audience, exposure rule and development decision. Ask it to trace one unfavorable answer back to the card and forward to a bounded repair. If buyers imagine a ready-to-eat product that actually needs preparation, the useful next step is to clarify or revise that offer and reassess understanding before progressing it on a favorable interest score.
A breakfast pot or family kit needs a research lead
In this hypothetical food-development brief, a team must choose a single-serve breakfast pot or family-size kit for a prototype. Both cards need comparable detail on occasion, contents, preparation, pack size and proposed price.
What the partner owns and what your team supplies
Work | Partner responsibility and brand input |
|---|---|
Design | Managed partner should agree: Instrument, assignment, quality checks and analysis plan Your team must supply or approve: Decision, feasible cards and progression criteria |
Audience / grounding | Managed partner should agree: Human recruitment or modeled-population construction, with evidence status Your team must supply or approve: Market, eligibility and shareable category evidence |
Readout | Managed partner should agree: Source-to-finding-to-recommendation walkthrough, including contradictory cases Your team must supply or approve: Commercial constraints and actual product facts |
Iteration | Managed partner should agree: What revisions and follow-up comparisons are included Your team must supply or approve: Which improved concepts are ready to compare |
Acceptance | Managed partner should agree: Saved stimuli, instrument, segment bases and assumptions in agreed format Your team must supply or approve: Confirmation that the result answers the brief |
Name the research lead who connects the concept comparison, prototype and physical research. A provider can coordinate specialists, or your team can own that work. Assign who resolves changes; a broad service list does not establish those responsibilities.
The 2025 ICC/ESOMAR Code places oversight with researchers for their work and responsibility with contributors for the activities they control. Ask who flags a prototype that no longer represents the tested offer.
The handoffs determine the missing skill
Handoff | Record and next owner |
|---|---|
Concept comparison to prototype brief | Keep: The offer version, preparation, contents, pack size and terms behind the recommendation. Next owner: The development owner confirms which offer can be made and identifies any changes. |
Prototype to physical research | Keep: What was actually made, the instructions people receive and the preparation or use question still open. Next owner: The relevant product-research specialist confirms suitable materials, participants and tasks. |
Physical research to development decision | Keep: The experience tested, its relationship to the original concept and any remaining commercial assumptions. Next owner: The agreed research lead connects the evidence, with the brand owner responsible for the investment decision. |
If the family-kit prototype needs an ingredient absent from its card, the development owner flags the change before physical sessions. The research lead decides whether preparation has changed enough to require a revised offer study. Testing the new kit cannot change what earlier buyers were told.
Recruit for the next task: the person choosing breakfast may differ from the person preparing it. A physical-use study needs suitable people, materials and tasks; a simulated profile cannot supply a preparation observation.
A favorable family-kit score can hide the wrong experience
Suppose the family kit leads on interest, but unaided answers describe ready-to-eat food while the product requires preparation. Resolve that mismatch before prioritizing the prototype. Keep the card, preparation question, coding rule and valid base with the finding.
Compare answers showing correct understanding with those imagining ready-to-eat food to diagnose the problem. These answer-defined groups are not randomized. If preparation is missing or unclear, repair the card, keep other facts fixed and recheck understanding. If the burden itself is unattractive, revise the product or positioning, save a new concept version and evaluate that offer.
For this breakfast decision, our managed concept testing service compares simulated reactions and preparation understanding to narrow the prototype brief. Physical preparation, taste and actual repeat purchase still need product or behavioral evidence.
The recommendation needs a working record
Retain questions, cards, display conditions, valid group bases, exclusions, assumptions and next actions. Label human and simulated sources. Check a diagnostic index against its reference data; do not relabel it as purchase probability.
Our published foldable-iPhone report illustrates simulated qualification and switching, rather than observed demand. Use it to inspect the path from source to finding to recommendation and the remaining evidence.
Zappi also documents professional services for tailored solutions, custom audiences and program support, alongside a separate synthetic screening route. Confirm the response source and responsibilities of the selected solution.
A Sapien study provides a managed modeled comparison. Agree audience grounding, task-relevant validation, interpretation and the remaining human or product evidence in scope. Physical preparation, taste and repeat purchase need their corresponding evidence. Retain the cards, instrument, response bases, assumptions, recommendation and included follow-up so the development team can act on the result.
When the CPG quotes buy different evidence
Return to the two $29 starter kits and the planning brief for 200 eligible human responses per concept. Suppose the replies offer recruited buyers, a modeled audience or a combination. These are hypothetical proposal structures, not supplier quotes or study results. Matching the headline response count doesn't make the purchases equivalent.
Keep the same audience definition and finished cards while reviewing the alternatives. Kit A's ready-to-use products and kit B's bottle and refills must retain their contents, preparation, one-time price and shipping terms. A provider that removes the price or simplifies away preparation is pricing a different concept test, even if its audience fits.
The source distinction also exists within a supplier's product range. For example, Kantar describes ConceptEvaluate AI as a model trained on consumer concept-test surveys that can screen concepts without exposing them to consumers. Selecting a supplier name alone doesn't identify whether this study collects fresh human answers or returns predictions.
Proposed evidence for the starter kits | What the proposal would supply | What to resolve before accepting |
|---|---|---|
200 eligible people assigned to A and 200 different eligible people assigned to B | The human first-reaction design requested in the planning brief, if the cards and question order are retained | Confirm recruitment feasibility, valid bases, interpretation and the included revision. A human survey still doesn't demonstrate cleaning performance or paid repeat purchase. |
200 modeled responses for A and 200 for B | A simulated comparison under the proposed audience and method | Identify the modeled results as such. If the development gate still requires the human comparison, obtain that work as a separate phase rather than mark it complete. |
100 human responses plus 300 modeled responses, presented as 400 combined answers | Two sources whose contribution to each concept and finding remains unclear | Ask for human and modeled bases by card, separate outputs and an explanation of any combined estimate. This is not 400 recruited people; quote the human work still needed for the agreed decision. |
A modeled route might suit an earlier job: investigating whether kit B's refill instructions need revision before paying for the full human comparison. Accepting that proposal means changing the purchased task explicitly. Specify the information change the screen should investigate, the audience context it uses and the recommendation the team will receive. Don't retain “200 human responses per concept” in the brief and then sign off modeled records as delivery against it.
For a combined proposal, ask which findings depend on fresh human answers and which depend on the model. If the provider combines them, request the method and uncertainty treatment rather than applying a human-survey margin of error to the total. A larger combined number doesn't explain how the modeled evidence affects the result.
The purchase decision now has a concrete basis. If the team still needs independent human reactions to the finished kits, choose a compliant human scope or price the missing phase alongside the modeled work. If it only needs to repair a concept first, buy that bounded task and retain the later requirement. Compare the full remaining plan, including who updates the card and who interprets conflicting evidence, before treating the cheaper first phase as the cheaper answer.
Select the route that finishes this brief
For the two finished offers, shortlist LaunchPad or a compatible Qualtrics program, then add Pollfish or Zappi when targeting or diagnostics are decisive. Compare the same independent-exposure brief. For a narrower pack preference, assess PickFu with the exact alternatives and audience. Escalate to managed support when design or interpretation remains unowned.
Accept the route when it can show the card, preserve the eligible base, separate understanding from appeal and support the planned decision. Use our concept testing guide to prepare the progression rule and our exposure design guide to choose the task.
For the wider workflow choice, use our AI market research tools guide.
Bring the concepts and the buyers you need to understand. Book a demo to discuss your concept comparison to explore how Sapien can compare modeled audience reactions, explain objections and help you decide what to develop or improve.
Questions to ask a research provider
- Who exactly will answer, and how are they recruited or built?
- What will you hand back: raw records, tables, a report or a recommendation?
- What validation have you published, for which tasks, and where can we inspect it?
- What does the whole project cost, including recruitment and analysis, and how long does it take?
- Who does the work on our side, and who on yours?
- What would make you tell us the study cannot answer our question?